
All episodes
Page 22 of 23
1,115 episodes

Build enterprise generative AI apps using Llama 3 at 1,000 tokens/s on the SambaNova AI platform
Sep 11, 2024 · 54:34
SambaNova’s Michelle Matern and Petro Milan present their full-stack AI platform, demonstrating how the SN40L RDU chip enables Llama 3 inference at 1,000 tokens per second. They introduce Samba-1, a composition of 92 expert models behind a single endpoint, and benchmark it against GPT-3.5 and GPT-4 on enterprise tasks like information extraction and text-to-SQL. The workshop then builds a RAG-based Q&A system using LangChain, Unstructured, E5-large-v2 embeddings, ChromaDB, and Llama-3-8B-Instruct at 1,000 tokens per second. Attendees set up the environment, load documents, and run inference with real-time metrics showing time to first token of 0.09 seconds and total inference time of 0.65 seconds.

Going beyond RAG: Extended Mind Transformers - Phoebe Klett
Sep 11, 2024 · 16:04
Phoebe Klett presents Extended Mind Transformers (EMT), a modification to transformer attention that lets models retrieve relevant memory tokens during generation without fine-tuning. EMT uses relative position embeddings (RoPE in LLaMA, ALiBi in MPT) to enable zero-shot generalization. On a counterfactual retrieval benchmark up to 16K tokens, EMT outperforms fine-tuned models and, combined with RAG, surpasses GPT-4. It provides granular citations by showing exactly which memory tokens were attended to, and reduces hallucinations via active learning: when token-level entropy signals uncertainty, the model retrieves more memories. EMT is open-sourced on Hugging Face and GitHub with configurable parameters like stride length, top K, similarity masking, and unknown token elimination.
Judging LLMs: Alex Volkov
Sep 9, 2024 · 18:39
Alex Volkov, as an LLM judge from 2034, humorously judges AI engineers on their development practices, emphasizing the importance of tracing, iterative prompt engineering, and robust evaluation pipelines. He finds Daniel guilty of deploying without logging, Sasha guilty of premature fine-tuning without prompt iteration, and Morgan guilty of ignoring AI news—commuted to attending ThursdAI. Francisco’s overreliance on programmatic evals leads to a legal loss, while Maxime is 'awesome' for using Weights & Biases Weave. Alex concludes with a primer on evaluation methods: programmatic, human-in-the-loop, and LLM-as-judge, stressing the need to validate validators and create custom criteria. He promotes Weave for tracing and evals, and ThursdAI for staying updated.

Pydantic is STILL all you need: Jason Liu
Sep 6, 2024 · 15:21
Jason Liu returns to the AI Engineer World's Fair to argue that Pydantic (and his library Instructor) is still all you need for structured output with LLMs. He shows that the core API—response_model, streaming with iterables, and partials for real-time validation—remains unchanged, now supporting Ollama, LlamaCPP, Anthropic, Gemini, and more. Liu demonstrates validators that enforce rules like uppercasing names or verifying receipt totals, reducing errors with automatic retries. He applies structured output to RAG: using a Search model with optional date ranges and source selection, and a Response model with follow-up questions and validated URLs. For extraction, he creates classifiers using Literal types, meeting summaries with action items, and even tables as Pandas DataFrames via custom type hints. Liu’s key takeaway is that one retry often suffices, and as models get faster and smarter, structured output makes LLMs compatible with classical programming—turning generative AI into generating data structures defined by the developer.

Hyperspace More Nodes Is All You Need: Nicolas Schlaepfer
Sep 4, 2024 · 5:48
Nicolas Schlaepfer introduces Hyperspace's decentralized AI network and new product, a node editor for power users that generates agentic plans via a DAG orchestration model (HyperEngine v3). The network, with over 15,000 nodes, leverages consumer devices rather than GPUs, running inference through Llama.cpp. The product combines prompt engineering, visual React flow, Python execution, and RAG-like web browsing, using Qwen 2 instruct for reasoning and LLaMA 3 70B for summarization. Schlaepfer emphasizes diverse open-source models and a virtual file system for agentic primitives. Availability via waitlist is announced later this week.

GraphRAG: The Marriage of Knowledge Graphs and RAG: Emil Eifrem
Aug 28, 2024 · 19:15
Emil Eifrem, Neo4j co-founder and CEO, argues that GraphRAG—combining knowledge graphs with vector search—significantly improves RAG application accuracy, ease of development, and explainability. Citing studies, he reports accuracy gains of 3x (Data.org), 75-77% (LinkedIn), and Microsoft's finding that GraphRAG enables answering entirely new question types. He demonstrates Neo4j's Knowledge Graph Builder, which auto-generates graphs from PDFs, Wikipedia, and YouTube, making graph creation accessible. Eifrem frames this as the next evolution in search after PageRank and Google's knowledge graph, urging developers to adopt GraphRAG for richer context and better AI outcomes.

Building State of the Art Open Weights Tool Use: The Command R Family: Sandra Kublik
Aug 26, 2024 · 15:03
Sandra Kublik of Cohere presents the Command R family of open-weight models optimized for retrieval-augmented generation and tool use. Released in March 2024, Command R and Command R+ achieved 150,000 Hugging Face downloads within two weeks and now serve nearly 500,000 developers. The models overcome RAG challenges such as prompt sensitivity and citation accuracy through post-training, delivering fine-grained citations and low hallucination. Cohere open-sourced a toolkit UI with plug-and-play components for RAG and tool use, supporting cloud, local, and Hugging Face access. The new Multi-Step API enables sequential reasoning with automatic retry and reflection. Command R+ matches GPT-4 Turbo and Claude Opus on complex reasoning while being three to five times cheaper, positioning it as a scalable enterprise solution.

Git push get an AI API: Ryan Fox-Tyler
Aug 23, 2024 · 45:01
Ryan Fox-Tyler and Matt Johnson Pint from Hypermode present a hands-on workshop demonstrating how to build and iteratively improve AI features using their platform, focusing on a GitHub issue triage app. They first illustrate the process with a multiplayer game (Hypercategories) that uses AI for classification and scoring. Then they build a trend summary function using OpenAI GPT-4 to summarize repository issues, and a classify issue function with a Hugging Face DistilBERT model for labeling issues as bug, feature, or question. Finally, they add natural language search for similar issues by creating an embeddings model (MiniLM) and a Hypermode collection, enabling vector search without external databases. The workshop emphasizes incremental iteration, mixing AI models with traditional code, and using Hypermode's automatic GraphQL generation and observability to speed development.

Hypermode Launch: Kevin Van Gundy
Aug 23, 2024 · 5:03
Kevin Van Gundy, founder of Hypermode, argues that iteration velocity is the compound interest of software and key to succeeding with AI, and presents Hypermode as a runtime that makes AI approachable by integrating models and data into AI functions with minimal friction. Drawing from his experience at Vercel, he explains how rapid iteration helped them win against competitors, and applies the same philosophy to AI development. Hypermode removes common pain points: it offers one-request RAG with in-memory embedding and search, model comparison and fine-tuning export, and strong defaults that work with existing stacks. The platform de-risks getting it wrong by making model switching and prompt changes frictionless. Kevin invites listeners to a workshop to build a demo and offers $1000 in Hypermode credits to get started.

Disrupting the $15 Trillion Construction Industry with Autonomous Agents: Dr. Sarah Buchner
Aug 22, 2024 · 5:32
Dr. Sarah Buchner, Founder & CEO of Trunk Tools, argues that vertical AI agents are the future, targeting the $15 trillion construction industry where 10% rework costs $1.5 trillion annually. Her company deploys an agent every 45 days, starting with TrunkText, a RAG-powered Q&A tool that saves field professionals 1-2 hours daily by accessing up to 3.6 million pages of documentation per skyscraper. The episode reveals how their system uncovers costly data discrepancies—such as a door needing power-actuated hardware that contradicts specs—and automatically generates RFIs to resolve them. Buchner insists RAG is commoditized, but keeping humans at the center with an army of agents solving real-world problems is the true impact. The talk highlights Trunk Tools' brain behind construction, backed by Sequoia, Accel, and others, and notes the company is hiring as it scales.

10x Development: LLMs For the working Programmer - Manuel Odendahl
Aug 21, 2024 · 1:14:46
Manuel Odendahl presents a workshop on using LLMs as a translation engine to achieve 10x development productivity, arguing that treating models as cultural rather than purely technological artifacts enables novel techniques like world simulation for code reviews and domain-specific language creation. He demonstrates concrete methods: regenerating responses, editing model outputs, clearing context frequently, and summarizing transcripts into actionable formats. Odendahl introduces his tool Prompto for managing code fragments and emphasizes that fundamental programming knowledge remains essential while API-specific details become less critical. The episode focuses on decomposing problems into language translation steps, using examples such as transforming meeting transcripts into GitHub issues and building applications by instructing the LLM to simulate itself as the app. Odendahl advocates for divergent thinking and human-centered output, noting that all generated artifacts should ultimately serve human understanding.

Building Reliable Agentic Systems: Eno Reyes
Aug 20, 2024 · 18:14
Eno Reyes, CTO of Factory.ai, explains how his team builds reliable agentic systems—called Droids—for automating software development tasks by applying techniques from robotics and control systems to handle planning, decision making, and environmental grounding. Reyes describes a pseudo-Kalman filter that passes intermediate reasoning through plan steps, converging reasoning but risking error propagation. He advocates for explicit plan criteria and hard-coded logic to improve reliability, despite reducing generalizability. On decision making, he recommends consensus mechanisms like self-consistency, explicit reasoning with checklists, fine-tuning for out-of-distribution decisions, and simulation via Monte Carlo tree search. For environmental grounding, he emphasizes building custom AI computer interfaces for domain-specific workflows, designing explicit feedback processing (e.g., parsing CI/CD logs), balancing bounded exploration with long-context models, and incorporating human guidance to boost reliability from 30–40% to 90–100%.
Building with Anthropic Claude: Prompt Workshop with Zack Witten
Aug 17, 2024 · 1:34:56
In this live prompt engineering workshop, Anthropic's Zack Witten and Jamie Neuwirth demonstrate techniques for improving Claude prompts in real time, using the Anthropic console. They show that XML tags clearly separate prompt sections, that placing instructions after information improves adherence, and that prefilling assistant responses with opening JSON or tags reliably forces JSON output without preamble. Witten advises using stop sequences and code to handle formatting rather than over-prompting, and emphasizes that few-shot examples—especially contrastive pairs with reasoning—drive more improvement than any other technique. The workshop covers role-playing multiple personas by routing via code, mitigating hallucinations by extracting quotes before summarization, and grading translations with chain-of-thought and fine-grained examples.

Running AI Application in Minutes w/ AI Templates: Gabriela de Queiroz, Pamela Fox, Harald Kirschner
Aug 14, 2024 · 1:29:02
In this workshop, Microsoft's Gabriela de Queiroz, Pamela Fox, and Harald Kirschner show how to deploy AI applications in minutes using AI templates, Azure OpenAI proxy, and GitHub Codespaces. They walk through deploying a simple chat app, then two RAG applications: one that queries a Postgres database with SQL filtering, and another that performs RAG on unstructured documents using Azure AI Search. Key decisions include using async frameworks like Quart and FastAPI, token-based chunking, and hybrid retrieval with semantic reranking for best results. They stress the importance of running evaluations with hundreds of samples and share production insights from Copilot Chat, where TFIDF sparse indexing and LLM reranking are used. The session includes free Azure credits and a proxy to bypass Azure OpenAI approval, allowing attendees to deploy everything without spending their own money.

Decoding the Decoder LLM without de code: Ishan Anand
Aug 9, 2024 · 17:08
Ishan Anand demonstrates how decoder-based LLMs like GPT-2 work internally using a fully functional spreadsheet implementation. He explains tokenization (e.g., 're-injury' splitting into 'rain' and 'injury' due to subword units), 768-dimensional embeddings, multi-headed attention where tokens look backward (e.g., 'he' focuses 0.48 on 'Mike'), and the multi-layer perceptron with matrix multiplies (MMULT). He shows residual connections creating an information superhighway and uses logit lens to reveal layer-by-layer predictions (e.g., 'Wednesday' appears early but only rises to top probability at later layers). Finally, he injects a sparse autoencoder feature vector for 'Jedi' into the residual stream, steering GPT-2 to output 'lightsaber' instead of 'phone', and contrasts this with alternative steering methods like representation engineering and activation steering.

Using agents to build an agent company: Joao Moura
Aug 8, 2024 · 13:46
Joao Moura, founder of crewAI, explains how he used AI agents to build his own company, sharing that over 10.5 million agents were executed with crewAI in the last 30 days. He describes starting by building a marketing crew that automated LinkedIn and content creation, which generated 10x more views in 16 days, then a lead qualification crew that led to 150+ customer calls in two weeks. Moura details new features: code execution with a single flag, trainable crews for consistent results, support for third-party agents, and crewAI Plus for deploying crews as auto-scaling APIs in minutes. He emphasizes starting simple with low-risk, high-impact use cases and encourages attendees to bring agents into production now.

What's new from Anthropic and what's next: Alex Albert
Aug 5, 2024 · 13:38
Alex Albert, Head of Developer Relations at Anthropic, argues the industry is in a 'magic star icon phase'—tacking AI onto existing products—and urges rebuilding from the ground up. He announces Claude 3.5 Sonnet, which scores 64% on pull request evals (vs 38% for 3 Opus), with 200k context, vision improvements, and pricing at $3/M input and $15/M output tokens. New features include Artifacts for collaborative creation of code and React components from screenshots, Projects for team knowledge grounding, and an enhanced ToolUse API supporting hundreds of tools and structured JSON output. Future models (3.5 Haiku/Opus) will be smarter, cheaper, and faster; a steering API for interpretability allows clamping feature values to control outputs.

How Codeium Breaks Through the Ceiling for Retrieval: Kevin Hou
Jul 31, 2024 · 18:42
Kevin Hou, AI engineer at Codeium, argues that embedding-based retrieval is hitting a ceiling for AI code generation and that Codeium breaks through by throwing large language models directly at the problem via a system called MQuery. He outlines the limitations of long context, fine-tuning, and embeddings, noting that embeddings are cheap but fail to reason over multiple documents needed for real-world coding tasks. Codeium developed a product-driven benchmark using recall 50 and commit-message datasets to measure retrieval quality. Because Codeium is vertically integrated—training custom models and building its own infrastructure—it can afford to run thousands of LLM calls in parallel per query, giving users 100x more compute than competitors. MQuery retrieves context from thousands of files in seconds, resulting in more accepted completions and better chat satisfaction. Hou compares this shift to autonomous driving: early heuristics like embeddings are giving way to large models that handle more data directly.

Emergence Launch: AI Agents and the future enterprise: Dr. Satya Nitta
Jul 31, 2024 · 5:41
Dr. Satya Nitta introduces Emergence, an R&D-led AI company spun out of IBM Research with talent from Google Brain, Alexa, and Meta, focused on advancing AI agents for enterprise. The company's core product, the Orchestrator Agent (G8, launching in August), plans, acts, and verifies across multiple LLMs and agents to automate complex workflows like claims processing. Emergence also develops Agent E, an open-source web agent that tops the Web Voyager benchmark by autonomously controlling the web. Nitta emphasizes the company's R&D on self-improvement agents, AI planning and reasoning, and agent-oriented programming, with applications in enterprise RPA and document processing. The goal is to enable enterprises to build and deploy autonomous agents that drive productivity by operating software and web browsers.
Low Level Technicals of LLMs: Daniel Han
Jul 31, 2024 · 2:52:26
Daniel Han of Unsloth explains how to find and fix bugs in open-source LLMs like Gemma, Phi-3, and Llama, covering tokenizer issues, architecture pitfalls, and finetuning optimizations. He details the eight Gemma bugs Unsloth fixed, including a critical RoPE downcasting error that broke positional encoding, and a 2048 sliding window bug in Phi-3. Han walks through transformer internals: attention masking, layer norms, RoPE embeddings, and SwiGLU activation, showing how to derive gradients for custom kernels. He demonstrates Unsloth's 2x faster finetuning with 70% less memory via Triton kernels, and introduces new features: automatic Ollama model file creation, CSV fine-tuning with merged columns, and chunked cross-entropy for large vocabularies. The session includes live Q&A on learning rate schedules, precision trade-offs, and mechanistic interpretability.

Fixing bugs in Gemma, Llama, & Phi 3: Daniel Han
Jul 31, 2024 · 17:42
Daniel Han of Unsloth details eight bugs found in Llama 3, including double BOS tokens, untrained tokens in the base model, and pad tokens equaling EOS tokens, which cause infinite generations. He explains how Unsloth automatically fixes these issues and offers a free Colab notebook for fine-tuning with Ollama. Han also covers tokenization fixes for Gemma and a sliding window bug in Phi-3, emphasizing the importance of correct chat templates and avoiding double BOS tokens. The episode provides concrete code examples and best practices for fine-tuning open-source LLMs to avoid common pitfalls.

Copilots Everywhere: Thomas Dohmke and Eugene Yan
Jul 26, 2024 · 18:22
GitHub CEO Thomas Dohmke shares the Copilot origin story from 2020 lockdown demos of GPT-3's Codex, its early 72 NPS despite hallucinations, and how it now writes half the code in enabled files. He details Copilot's expansion beyond IDE auto-completion to Chat and the new Copilot Workspace, which takes a GitHub issue and generates a plan and code changes, keeping humans in the loop. Dohmke argues Workspace helps non-developers like product managers see implementation details and size tasks. He defines an agent as an 'AI dishwasher' that autonomously handles drudge work like security backlogs, and urges developers to embrace AI tools to bring fun back into software development.

Unlocking Developer Productivity across CPU and GPU with MAX: Chris Lattner
Jul 25, 2024 · 18:33
Chris Lattner, CEO of Modular, presents MAX, a unified AI framework that accelerates Gen AI inference by combining CPU and GPU programming into a single Pythonic model, and Mojo, a new programming language that extends Python to systems programming with 100–1000x speedups. Lattner argues that current fragmentation across PyTorch, ONNX, TensorRT, and hardware-specific libraries slows innovation, and MAX replaces the entire stack—including cuDNN and Intel MKL—with a consistent, compiler-driven approach. He demonstrates that MAX's Int4/Int6 quantization achieves 5x faster performance than llama.cpp on cloud CPUs, and that its GPU matrix multiplication beats NVIDIA's cuBLAS by up to 30%. Mojo enables developers to write for loops and tokenizers (e.g., for LLaMA 3) in Python-like syntax without dropping to C++ or Rust. MAX is free and available now for CPU inference; GPU support launches in September with early access via Discord.

From Software Developer to AI Engineer: Antje Barth
Jul 24, 2024 · 19:48
Antje Barth, a Principal Developer Advocate for generative AI at AWS, outlines five practical steps from software developer to AI engineer: understanding foundation models, getting hands-on with AI developer tools like Amazon Q Developer, prototyping with models via Amazon Bedrock, integrating agents, and staying up to date with community events. She demonstrates Amazon Q Developer's ability to generate, explain, and transform code, reducing unvaluable tasks from 70% to focus on creative work. Barth introduces Amazon Bedrock's unified Converse API for standardized model invocation across providers like Anthropic's Claude 3.5 Sonnet, and shows how agents can be built to control a Minecraft bot through reasoning and tool use. The episode concludes with the announcement of the AI Engineering Hub at the AWS loft in San Francisco for community workshops and events.

Lessons From A Year Building With LLMs
Jul 19, 2024 · 35:21
The six authors of the O'Reilly article "Lessons From A Year Building With LLMs" — Bryan Bischof, Jason Liu, Hamel Husain, Eugene Yan, Shreya Shankar, and Swix — argue that the model itself is not a moat and that success comes from continuous improvement centered on evals and data. They stress that AI engineers should treat models as SaaS, quickly swapping for better ones, and focus on product and user interactions. The talk warns against toxic practices like prematurely hiring ML engineers without data or blindly adopting tools, advocating instead for deliberate eval practice and data literacy. On tactics, they compare LLM-as-judge (quick to prototype) vs fine-tuned evaluators (more precise and faster), and emphasize looking at real user data regularly with automated guardrails. Ultimately, they conclude that going from demo to production requires sustained investment in infrastructure and evaluation, echoing MLOps lessons from a decade ago.

Open Challenges for AI Engineering: Simon Willison
Jul 17, 2024 · 18:49
Simon Willison argues the GPT-4 barrier has been broken as GPT-4o, Claude 3.5 Sonnet, Gemini 1.5 Pro, and open models like LLaMA 3 70B now compete, making GPT-4-class models a commodity. He highlights the AI trust crisis with examples of Dropbox and Slack being falsely accused of training on user data, and notes Anthropic trained Claude 3.5 Sonnet without customer data. Willison warns about prompt injection vulnerabilities, citing the Markdown image exfiltration bug affecting six major chatbots, and defines slop as unreviewed AI-generated content, calling for accountability and responsible use patterns.

Llamafile: bringing AI to the masses with fast CPU inference: Stephen Hood and Justine Tunney
Jul 16, 2024 · 17:25
Stephen Hood and Justine Tunney present Mozilla's Llamafile project, which turns AI model weights into single-file executables that run on any OS and CPU without installation, democratizing access to AI. They claim CPU inference can match GPU performance through techniques like outer-loop unrolling in matrix multiplication and using a GPU-like programming model with sync threads, achieving 30-500% speed increases. Justine demonstrates a summarization task where the optimized version completes in seconds versus the old version's many seconds. Hood announces the Mozilla Builders accelerator offering $100,000 in non-dilutive funding for open-source local AI projects, emphasizing that individuals and small groups can still make impactful contributions in AI.
The Future of Knowledge Assistants: Jerry Liu
Jul 13, 2024 · 16:55
Jerry Liu, CEO of LlamaIndex, explains how to move beyond simple RAG to build production-grade knowledge assistants. He details three steps: advanced data processing with LlamaParse for accurate PDF parsing, single-agent flows with query planning and tool use, and multi-agent task solvers via the newly announced Llama Agents framework. Llama Agents treats each agent as a deployable microservice that communicates through a central API, enabling specialization, parallelism, and easier production deployment. Jerry also highlights that naive RAG is insufficient for complex queries, and that good data quality—like proper parsing of tables and charts—is essential to reduce hallucinations.

The Making of Devin by Cognition AI: Scott Wu
Jul 11, 2024 · 20:04
Scott Wu, co-founder and CEO of Cognition AI, demonstrates Devin, a fully autonomous AI software engineer that builds and deploys working applications from plain English instructions, sharing the early lessons and vision behind the product. Devin built a name game website for the AI Engineer World's Fair in minutes, iterating on feedback to hide names, add a streak counter, and deploy the final version. Cognition uses Devin internally for features like a search bar and dashboards; Wu notes that engineers typically spend 80–90% of time on implementation, but Devin frees them to focus on architecture and problem-solving, making them 5–10x more productive while increasing overall demand for software. He also highlights the UX challenges of agents, which require new interactions beyond text completion, and notes that access to Devin is expanding via a waitlist.

From Text to Vision to Voice Exploring Multimodality with Open AI: Romain Huet
Jul 10, 2024 · 23:39
OpenAI's Romain Huet demonstrates GPT-4o's real-time audio, vision, and screen-sharing capabilities at the AI Engineer World's Fair, showing how the omni-model achieves human-like conversational latency, understands emotion, and can be interrupted naturally. He walks through live demos of ChatGPT Desktop recognizing drawings, reading book pages, and pair-coding a responsive travel app using Tailwind CSS. Huet also previews Sora's text-to-video generation and OpenAI's unreleased Voice Engine, which can clone a voice from seconds of audio and translate it into multiple languages while preserving the original speaker's tone. He outlines OpenAI's four focus areas: advancing textual intelligence, faster/cheaper models (GPT-4o is twice as fast as GPT-4 Turbo at half the price), model customization via fine-tuning, and enabling multimodal agents. The talk emphasizes that today's models are the dumbest they'll ever be and urges developers to build for a future where AI works across text, voice, and video.

The Code AI Maturity Model and What It Means For You: Ado Kukic
Feb 13, 2024 · 7:58
Ado Kukic, Director of DevRel at Sourcegraph, presents the Code AI Maturity Model, a framework comparing AI coding assistant autonomy to SAE vehicle levels. He argues that 92% of developers now use Code AI tools, up from 1% a year ago, and predicts 99% of code will be written by AI in 5 years. The model defines six levels: Level 0 (manual coding), Level 1 (AI-generated snippets from developer intent), Level 2 (codebase-aware completions, e.g., suggesting Axios in a Node.js project), Level 3 (AI builds full features from high-level requirements, like adding authentication), Level 4 (AI proactively handles tasks, such as auto-fixing bugs via PRs), and Level 5 (AI handles the entire software lifecycle with minimal human oversight). The talk contextualizes each level with autonomous driving parallels, emphasizing that the industry is currently transitioning between Levels 1–3, with Level 5 representing full AI-led code generation.
How to Become an AI Engineer from a Fullstack Background - Reid Mayo
Feb 2, 2024 · 10:19
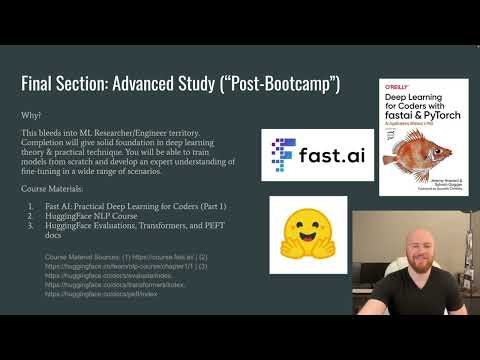
Reid Mayo presents a step-by-step syllabus to transition from fullstack engineer to AI engineer, covering generative AI foundations, prompt engineering, LangChain, fine-tuning, and cost-effective open-source model deployment. The syllabus starts with Cohere's LLM overview, then dives into prompt engineering via Elvis Seravia's guide and Learn Prompting org docs. It emphasizes LangChain as the glue layer for modular AI systems, with tutorials from Mayo Ocean. Evals are treated as software tests using OpenAI's cookbook. Fine-tuning is taught via OpenAI's cookbook and then open-source LLaMA 2, with a specific case study showing a $19 fine-tuned LLaMA 2 matching OpenAI's $24,000 model on a target task. The boot camp ends with advanced deep learning courses from FastAI and Hugging Face for further mastery.
Using AI to Build an Infinite Game: Jeff Schomay
Feb 1, 2024 · 11:08
Jeff Schomay built a game with 100% AI-generated content, using OpenAI's fine-tuning to generate JSON scene definitions and Leonardo to create stylistically consistent images. He fine-tuned a model on 50 examples for about $1–$2, enabling shorter prompts and reliable JSON output. To maintain visual consistency across scenes with varied elements (people, animals, buildings), he trained multiple image models. He implemented a caching pipeline that prefetches scenes to compensate for 10–30 second generation times, ensuring a smooth player experience. The final game procedurally generates every scene and image, so each playthrough is unique.
GPT Web App Generator - 10,000 apps created in a month: Matija Sosic
Jan 26, 2024 · 9:23
Matija Sosic, CEO and co-founder of Wasp, demonstrates how his team built mage, a GPT-powered full-stack web app generator that produced over 10,000 applications in one month. Mage specializes in generating React, Node.js, Prisma, and Wasp apps from plain English descriptions, thanks to three key factors: specialization in full-stack web apps, leveraging Wasp's high-level declarative configuration to reduce boilerplate and errors, and an automated error-fixing phase. A typical app uses 25,000 to 60,000 tokens and costs 10 to 20 cents by combining GPT-3.5 for implementation and GPT-4 for planning, versus $1–$2 with GPT-4 alone. Mage serves as a highly customized cross-starter, with current limitations around lack of interactive debugging, which is planned next. Future directions include live debugging and potentially fine-tuning an LLM for Wasp.

Storyteller: Building Multi-modal Apps with TS & ModelFusion - Lars Grammel, PhD
Jan 23, 2024 · 7:30
Lars Grammel presents Storyteller, a kid's story generator built with TypeScript and his ModelFusion library, which orchestrates multiple AI models to turn voice input into narrated audio stories with images. The app transcribes speech via OpenAI Whisper in 1.5 seconds, generates a story outline with GPT-3 TurboInstruct in 4 seconds, and then runs title, image, and audio generation in parallel. For consistency, it uses GPT-4 with a low temperature to produce structured story passages, and streams partial results so narration can begin before the full story is ready—addressing the 1.5-minute full generation time. Voices are selected by embedding speaker descriptions and retrieving matching ElevenLabs voices filtered by gender. Image prompts are extracted from the story via GPT-4 and rendered with Stability AI's Stable Diffusion XL. The result is a responsive, multi-modal app that lets users listen while the server continues processing.

Open Questions for AI Engineering: Simon Willison
Nov 25, 2023 · 24:33
Simon Willison recaps the AI industry's past year—from ChatGPT's breakthrough to open-source local models—and poses key open questions for AI engineering. He argues that ChatGPT's chat interface, while popular, is a poor fit for advanced use, urging better UIs like his command-line tool LLM. He celebrates Meta's Llama release as a 'stable diffusion moment' for language models and highlights the rise of small, locally-run models such as Replit's 3B model, asking how small models can remain useful. On security, he warns that prompt injection remains unsolved after 13 months, limiting what can safely be built. He champions ChatGPT's Code Interpreter (which he dubs 'Coding Intern') as the most exciting tool, able to write and compile C code on a phone, and argues that LLMs flatten the learning curve, making programming accessible to more people. He concludes by urging the community to build tools that enable anyone to automate tedious tasks.

Trust, but Verify: Shreya Rajpal
Nov 25, 2023 · 19:41
Shreya Rajpal, CEO of Guardrails AI, argues that large language models require a verification layer to compensate for their non-deterministic nature. She explains that while prototyping works, production apps fail due to hallucinations, prompt injections, and structural errors. Guardrails AI is an open-source framework that wraps LLMs with a validation suite: on output, it checks constraints like provenance (grounding in a source), profanity, and competitor mentions. On violation, it re-asks the model to self-correct or falls back to specified policies. Rajpal demonstrates with a chatbot example where a provenance guardrail catches a hallucinated password setting, then guides the model to a correct answer grounded in help center articles. The framework also supports custom validators, automatic prompt compilation from checks, and integration with external systems like sandboxed SQL databases for code generation.

Harnessing the Power of LLMs Locally: Mithun Hunsur
Nov 22, 2023 · 17:09
Mithun Hunsur presents llm.rs, a Rust library for running large language models locally, arguing it gives developers ownership, lower latency, and privacy compared to cloud APIs. He explains how quantization makes inference viable on consumer hardware, and shows that llm.rs supports architectures like LLaMA and Falcon through a unified interface. Practical code examples demonstrate customization, and community projects like LocalAI and LLMchain illustrate real-world use. Hunsur shares his own date-extraction pipeline, fine-tuning a small model with GPT-3 data to replace expensive cloud calls. He also cautions about hardware requirements, trade-offs between speed and quality, and ecosystem churn from rapid innovation.

The Weekend AI Engineer: Hassan El Mghari
Nov 22, 2023 · 21:49
Hassan El Mghari shares how he built viral AI apps like RoomGPT and AI Commit, arguing that simple off-the-shelf APIs and focused weekend sprints can attract millions. He describes building 11 side projects in a year, which grew from 20,000 visitors to over 8.5 million unique visitors and 2.8 million sign-ups. Key projects include RoomGPT, which used ControlNet for room redesign and reached 6 million visitors, and AI Commit, an open-source CLI tool adopted by 30,000 developers. He emphasizes using tools like the Vercel AI SDK and v0.dev to accelerate development, making apps free and open source to drive growth, spending 80% of time on UI, and launching quickly with minimal fine-tuning.

120k players in a week: Lessons from the first viral CLIP app: Joseph Nelson
Nov 22, 2023 · 15:59
Joseph Nelson (Roboflow CEO) details building paint.wtf, a viral AI Pictionary game using OpenAI CLIP that attracted 120,000 players in its first week, peaking at 7 submissions per second. The architecture uses GPT-3 to generate prompts, a browser canvas for drawing, and CLIP to judge similarity between text and image embeddings. Key lessons include CLIP's ability to read text, requiring a moderation hack that penalizes images more similar to handwriting than the prompt; CLIP's conservative similarity scores (ranging 8% to 48%); and the necessity of using CLIP itself to block NSFW content. Nelson also live-codes a minimal MVP in under 50 lines of Python using Roboflow's open-source inference server, demonstrating CLIP embedding and cosine similarity. The talk underscores foundation models' new paradigm of open-set understanding.
Building Production-Ready RAG Applications: Jerry Liu
Nov 15, 2023 · 18:35
Jerry Liu, CEO of LlamaIndex, explains how to productionize Retrieval Augmented Generation (RAG) systems by moving beyond naive implementations. He identifies key challenges: low retrieval precision causing hallucination, low recall from insufficient top-K, and lost-in-the-middle problems. Liu advocates starting with 'table stakes' improvements like tuning chunk sizes (showing optimal values per dataset), adding metadata filters (e.g., year=2021 for SEC 10Q queries), and hybrid search. More advanced techniques include 'small-to-big retrieval', embedding smaller chunks for precision then expanding windows for synthesis, and using reranking to improve recall. Finally, he explores agent architectures where each document becomes a tool for summarization or QA, and fine-tuning—generating synthetic query datasets from raw text to fine-tune embeddings, or distilling GPT-4's chain-of-thought into GPT-3.5 Turbo for better reasoning.

Retrieval Augmented Generation in the Wild: Anton Troynikov
Nov 15, 2023 · 12:20
Anton Troynikov, co-founder of Chroma, explains that retrieval augmented generation (RAG) requires more than simple vector search—it needs human feedback, self-updating memory, and agent interaction to handle dynamic data. He covers challenges like choosing the right embedding model, chunking strategies (including using language model perplexity), and determining result relevance without distractors. Chroma is building a horizontally scalable cluster, a cloud technical preview by December, and support for multimodal data. The episode argues that a capable memory system is key to making AI agents truly functional, citing the Voyager paper where Chroma stored learned skills for Minecraft agents.
Domain adaptation and fine-tuning for domain-specific LLMs: Abi Aryan
Nov 14, 2023 · 25:09
Abi Aryan's talk covers domain adaptation and fine-tuning for large language models, contrasting prompting, RAGs, and three fine-tuning methods: adaptive, behavioral, and parameter-efficient. Adaptive fine-tuning adds small adapter modules (0.15% of parameters) for new domains like biochemical engineering; behavioral fine-tuning optimizes label space for a single task; and parameter-efficient methods like LoRA and QLoRA reduce model size via low-rank adaptation and four-bit precision, ideal for low-resource devices. Aryan emphasizes data quality—deduplication reduces memorization—and practical tips: batch size of 32 or 64, starting with 100 epochs, using Adam optimizer, gradient checkpointing for memory savings, and in-context learning with dynamic examples to handle drift. Evaluation should combine metric-based (Bleu, Rouge), tool-based (Weights & Biases), model-based, and human-in-the-loop approaches, though full pipeline considerations (data collection, base model choice, storage) are critical for robust applications.

Pragmatic AI with TypeChat: Daniel Rosenwasser
Nov 14, 2023 · 18:34
Daniel Rosenwasser, TypeScript program manager, introduces TypeChat, an experimental library that uses TypeScript type definitions to guide and validate unstructured LLM output into structured JSON for traditional apps. He demonstrates a coffee shop ordering system where types define the schema, showing how the library can handle ambiguous inputs like 'a purple gorilla' by including unknown text for recovery. TypeChat also generates programs as JSON using a fake language to safely script multi-step operations, avoiding sandboxing issues from real code. A Python prototype extends the same approach, with examples like CSV data manipulation via a class-based API. The library aims to make AI tools accessible to all engineers by leveraging types they already use.

Building Reactive AI Apps: Matt Welsh
Nov 9, 2023 · 17:02
Matt Welsh announces AI.JSX, an open-source TypeScript framework he describes as 'React for LLMs,' which lets developers build reactive AI applications by composing JSX components that render to an LLM rather than the DOM. He argues AI.JSX makes LLM app development accessible to JavaScript developers, not just Python back-end engineers, by handling RAG, tool invocation, and real-time voice interaction out of the box. Welsh demonstrates parallel streaming of multiple LLM calls for story generation, a kid-safe wrapper component that rewrites content, and a 10-line RAG implementation. He showcases a live voice demo where an AI takes a donut order with sub-second latency, powered by Fixie's cloud platform for hosting, managed RAG pipelines, and conversational state. He emphasizes the framework's full React integration and ability to generate UI from AI, positioning AI.JSX as a simplification for building sophisticated LLM-powered apps.

AI Engineering 201: The Rest of the Owl
Nov 8, 2023 · 56:57
Charles Frye, instructor of the Full Stack LLM Bootcamp, presents essential patterns for building language user interfaces (LUIs), arguing that while RAG chatbots are the 'to-do list app' of AI engineering, structured outputs via function calling (e.g., OpenAI's JSON schema, Instructor library) improve robustness, and agents with memory (like generative agents or Voyager in Minecraft) represent the true AI frontier. He emphasizes the need for hybrid search combining vector and keyword retrieval (citing Vespa, Postgres, Redis), and warns that monitoring and evaluation are the hardest engineering challenges: monitoring user behavior, latency quantiles (especially 99th percentile), and costs must be paired with observability tools like Honeycomb or Gantry, while evaluation often requires iterated decomposition or using LLMs as evaluators (GPT-4 as 90th percentile crowd worker). The episode concludes that shipping to learn — starting with production data to generate tests — is the dominant engineering mindset, and that the field is still filling in the gaps between inference and full product value.

Move Fast Break Nothing: Dedy Kredo
Nov 8, 2023 · 13:01
Dedy Kredo, co-founder and CPO of CodiumAI, argues that code generation needs a GAN-like architecture with a separate code integrity critic, and that behavior coverage is a more useful metric than code coverage. He demonstrates CodiumAI's IDE extensions (200,000 installs) on the open-source AutoScraper project (5,000 GitHub stars with no tests), automatically mapping behaviors, generating tests for happy paths and edge cases, and using reflection to auto-fix failures. The tool then enhances code with deep improvements (performance, security) and, via a PR assistant, catches a forgotten API key vulnerability. Kredo closes with a personal note about the Hamas attack on Israel, showing his co-founder on reserve duty while CodiumAI usage continues to rise.

The AI Evolution: Mario Rodriguez, GitHub
Nov 7, 2023 · 19:32
Mario Rodriguez, VP of Product at GitHub, recounts the history and future of GitHub Copilot, the first at-scale AI programmer. Copilot now serves over 20,000 organizations and 1 million-plus developers, generating over $100M in ARR, with 46% of code written via completions. He shares insider lessons: ghost text, low latency under 100 milliseconds, and prompt engineering were key to success. He warns that 'syntax is not software' and that global presence and offline/online scorecards are essential at scale. Looking ahead, Rodriguez envisions moving from procedures to goals and constraints, enabling AI to reason on code, and designing immersive UIs for human-AI collaboration. He concludes that GitHub has evolved from a version control system into an end-to-end platform infused with AI.

The AI Pivot: With Chris White of Prefect & Bryan Bischof of Hex
Nov 7, 2023 · 35:16
Chris White (CTO of Prefect) and Bryan Bischof (Head of AI at Hex) detail how their non-AI startups successfully pivoted to integrate AI, arguing that ruthless prioritization and deep product integration are key. White explains Prefect built the open-source Marvin project to learn from LLM experimenters, while adding AI features like error summaries to its core orchestration product, but had to restrain over-enthusiasm from engineers. Bischof describes Hex's Magic feature as an augmentation, not a separate product, and explains they built their own evaluation system but chose not to build a vector database, and killed a promising feature called Crystal Ball to avoid splitting the product experience. They both emphasize machine-to-machine interfaces and typed outputs, and caution that the work is often tedious data engineering. Their hot takes: White says stop building chat interfaces, AI is a tool; Bischof warns that the journey is boring but worth it.

[Workshop] AI Engineering 201: Inference
Nov 7, 2023 · 1:43:16
Charles Frye, instructor of the Full Stack LLM Bootcamp, leads a workshop on AI engineering inference, focusing on the build-versus-buy decision between proprietary and open models. He argues that proprietary models like OpenAI's GPT-4 and Anthropic's Claude are currently more capable but expensive, while open models like LLaMA 2 are less capable but offer hackability, though they may catch up if capabilities requirements saturate. Frye covers inference on end-user devices, noting that running models locally avoids network latency but faces tight memory and power constraints—e.g., a 7B parameter model requires 14 GB, too large for phone RAM. He explains inference-as-a-service (e.g., OpenAI, Replicate) versus self-serving on cloud GPUs or serverless platforms like Modal, highlighting that memory bandwidth is the bottleneck: GPUs have 1.5 TB/s memory bandwidth vs 312 TFLOPS compute, so batching is crucial for throughput. Frye also discusses inference arithmetic, custom silicon like TPUs which offer ~30% better efficiency but not drastic gains, and containerization challenges for GPU workloads.
Powered by PodHood