
All episodes
Page 1 of 23
1,115 episodes

Building ambitious software — Jonathan Kelley, Dioxus Labs & Cognition
Sep 11, 2026 · 19:14
Jonathan Kelley, founder of Dioxus Labs, whose cross-platform Rust app framework now has nearly 37,000 GitHub stars and an estimated 200 million end users and was acquired by Cognition, argues that AI coding agents have made code cheap but quality remains the scarce resource, so architecture now takes most engineering time. He traces Dioxus's five-year effort building everything from scratch, including the Blitz rendering engine with a browser-grade CSS engine lifted from Firefox and the Subsecond hot reload engine that patches running native code in about 100 milliseconds. When agents got good at Rust, his team maxed out their Claude Code subscriptions and produced tens of thousands of lines that mostly never cleared the merge bar, a failure mode he calls becoming a slop cannon. He credits agents for deeply integrated Kotlin and Swift build plugins shipped in two to three weeks, release checklists, backports, and documentation accuracy, while noting they write tests for any API but rarely the right ones, though they excel at fuzzing harnesses. Rust's learning curve, once fought, is now a feature because agents absorb the borrow checker and edge cases.
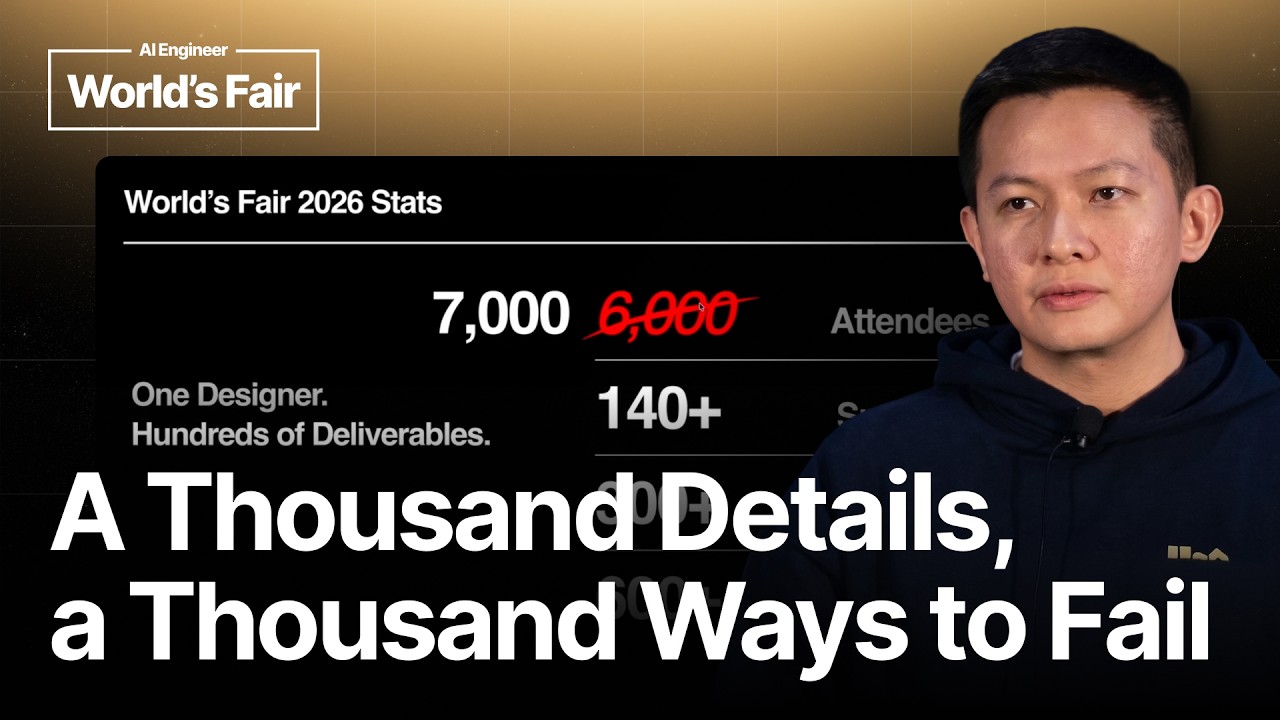
One Designer + AI. Hundreds of Deliverables. — Vincent Wendy, AI Engineer
Sep 10, 2026 · 16:48
Vincent Wendy, the sole senior creative designer at AI Engineer, explains how he alone designs for a conference that grew to 7,000 attendees, 140+ sponsors, 300+ speakers, and 600+ sessions. His five-part method—build the foundation first, make designs reusable, automate workflows, validate output, and remove friction—starts with a tightly defined design system so LLMs like Devin and GPT cannot invent their own font sizes, letting marketing build emails and flyers from the website alone. Room schedules once laid out by hand in Figma now pull fresh from live data via Devin, export to PNG, and ship to screens on a flash drive. A generator produces pixel-perfect announcement graphics and trading cards for all 300 speakers, and Devin matches photographers' shots to the right speaker, like identifying Jason Liu. Devin also caught every missing sponsor logo on the 140-plus-logo lobby banner and the conference t-shirt, and added an edit button to the schedule tool the morning one was needed—so with tools no longer the constraint, having a real problem is the advantage.
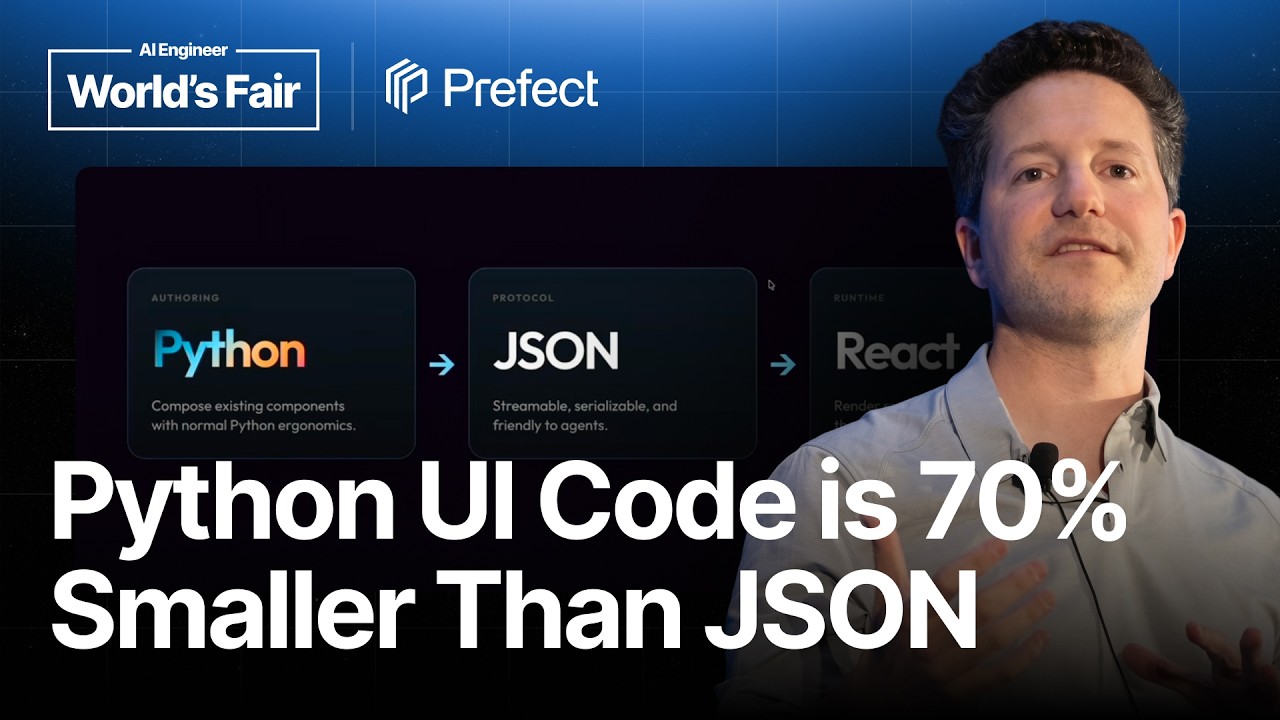
Generative UI... in Python? — Jeremiah Lowin, Prefect
Sep 10, 2026 · 17:38
Jeremiah Lowin, founder and CEO of Prefect and author of FastMCP, explains how MCP apps — a protocol extension introduced in January that lets tool results bypass the agent and reach users as HTML, CSS, and JavaScript — led him to build Prefab, a Python DSL for shipping UIs from MCP servers. Because FastMCP's users are mostly Python engineers in enterprises sharing tables, forms, and charts, he refused to pretend to ship React from Python and instead scoped the problem to composing pre-built components via nested context managers and reactive variables. Lowin argues the JSON serialization in the middle is the real point, since a serializable UI can be generated, received, or edited by an agent. His team also found the Python representation is about 70% smaller than JSON, so they now stream Python over the wire and convert it in a sandbox, and the Prefab docs are rendered entirely in Prefab with live-editable examples.

The Design-Code Roundtrip That Isn't — Jonathan Gordon, ReWeaver AI
Sep 10, 2026 · 18:37
Jonathan Gordon, founder of ReWeaver AI, argues the design-code roundtrip still doesn't exist: thirty years of developer tooling never closed the loop between design and engineering, and AI didn't fix it. After a vibe coding session where he caught an agent writing a risky innerHTML statement, he tested five tool setups for a bidirectional code-design loop and found every one lossy, with dropped bindings or design changes surviving while code didn't. He demos ReWeaver publicly for the first time, scanning generated code and a Figma canvas across nine dimensions including design consistency, performance, tokens, and accessibility, flagging issues like missing ARIA live regions that leave screen reader users with no announcement. In a 12-iteration experiment, pure model output started near 30% fidelity and decayed, while deterministic guardrails held quality up; it never reaches 100 because the last stretch is human judgment. His name for drift accumulating unwatched: the new tech debt.

The Spatial Harness: Bringing Agents to the Canvas — Max Drake, tldraw
Sep 10, 2026 · 18:52
Max Drake, product engineer at London's tldraw, argues coding agents excel because code is text in and text out, while canvas agents need engineering to understand and act in 2D space. tldraw, the whiteboard app and SDK behind canvases including Replit's, ships an MIT-licensed agent starter kit that teaches models to read a canvas from screenshot plus JSON and set their own todos, moving their viewport to explore. Fairies renders agents as figures you can throw and recolor; selecting several opens a group chat with an orchestrator assigning and reviewing work — you read ten agents' state at a glance, not a chat log. Last, a dependency graph of coding agents and a desktop build that lets agents script the editor — a colleague made it a window manager playing Pong with real windows.

ACP: The Universal Remote Control for AI Agents — Alex Hancock, Block
Sep 9, 2026 · 11:01
Alex Hancock, a Block engineer who works on the Goose harness and the MCP Rust SDK, argues agentic AI has a standard for agents reaching outward (MCP) but none for clients telling harnesses what to do — in the worst case one client per harness, like needing a different browser per website. His answer is ACP, the agent client protocol from Zed and JetBrains: JSON-RPC-based, carrying sessions, user messages, tool calls, and permission requests, and extensible via underscore-prefixed custom methods so shared patterns can move onto a standards track. He demos Zed and a Poolside terminal client driving the same Goose agent, plus a new HTTP and websocket remote transport. With remote transports for protocol, MCP, and models, all four pieces of the stack become independently placeable.

MCP Apps: Give the Model Data, Give the User a UI — Dustin Mihalik, Indeed
Sep 9, 2026 · 15:34
Dustin Mihalik, technical fellow at Indeed, shares lessons from building MCP apps for Claude, ChatGPT, and Indeed's Career Scout job seeker agent, arguing that data must come before UI because a naive widget makes the product worse: a text-based job search prompted the model to run ten or fifteen searches, filter results, and assemble a table, while a rendering widget caused it to call the tool once and stop exploring. He lays out three rules: anything shown to the user must also reach the model as data, or every follow-up question fails; the tool description must state a UI exists, or the model narrates the same results underneath it; and, superseding the others, separate data processing from UI rendering. At Indeed that meant a plain search tool the model calls freely plus a render widget taking a list of IDs, so it can search 100 jobs, filter to five, and show only those, with interactions pushed back through update model context. He closes on small composable tools and letting the render tool carry the model's reasoning about why a result fits.

How long can your skills be before your agent forgets what you told it? — Laurie Voss, Arize AI
Sep 9, 2026 · 22:26
Laurie Voss, head of developer relations at Arize AI and co-founder of npm, argues the 200-instruction ceiling for skills files collapsed 10x in a year. Rerunning the IFScale benchmark, which asks a model to write a report containing exact words and counts how many appear, he replicated last year's 200-to-300 drop, then watched current models ace it. He had to raise the test from 500 words to 10,000 before anything broke: the boundary now sits near 2,000 instructions, closer to 5,000 for the best. Failures diverged: DeepSeek forgets, Claude refuses when random words trip its safety filter, Gemini overthinks and answers nothing, and GPT-5.5 writes half a report then calls the request stupid. Compression is solved; verification—checking outputs with evals—is now the hard part.

Your agents lack context: Here's how to fix "You're absolutely right!" — Brandon Waselnuk, Unblocked
Sep 9, 2026 · 14:09
Brandon Waselnuk of Unblocked argues that AI-generated code should feel like it was written by someone who has been on your team for years, and that the gap is no longer intelligence but context. He traces how bad context compounds as teams move from tab completion to parallel and background agents, producing correction doom loops, wasted search tokens, and a review tax. Two common fixes stall: the curated context trap, where markdown files rot and someone must curate them for everyone, and the MCP plateau, where an agent may never call the server or stops at the first plausible answer due to satisfaction of search bias, missing last night's Slack correction. A context engine must resolve conflicts between an old architecture diagram and a fresh CTO Slack thread, personalize relevance, enforce permissions, and deliver token-optimized context. Running the same prompt with and without context cut tokens from 21 million to 10.8 million and finished about two hours sooner. He closes by demoing three open source tools, including a workshop that builds a relational context engine from scratch.

500 Skills, Zero Fine-Tuning: LinkedIn's Playbook for AI Agents — Ajay Prakash, LinkedIn
Sep 9, 2026 · 20:25
Ajay Prakash, senior staff software engineer at LinkedIn, explains how Contextual Agent Playbooks make coding agents reliable at enterprise scale, turning an on-call alert into a mitigated incident in minutes. Early vibe coding failed: agents trained on open source hallucinated across LinkedIn's 1,000 internal repos. An internal MCP server with code search, docs, and Jira fell short: tribal knowledge sat in stale wikis, context overloaded, and sessions started from scratch. Playbooks, instructions published as tools, work when self-contained and split into small referenced pieces, and agents open PRs to refresh stale ones. Since MCP degrades past 30 or 40 tools, everything surfaces behind three meta tools: search, get schema, execute, now 1,300 tools, 600 playbooks, 8,000 daily users.

It’s Tokens All The Way Down: How RLMs are Different — Kevin Madura, AlixPartners
Sep 9, 2026 · 20:48
Kevin Madura, director of advanced technology at AlixPartners, argues that recursive language models (RLMs) mark a fundamentally different way for LLMs to handle context: instead of attending to every token, the model treats its context as a variable in a Python REPL and delegates subtasks to sub-LMs, including itself. He traces RLMs to early work by Omar Khattab and Alex Zhang, citing the Oolong and BrowseComp benchmarks, where an RLM beats GPT-5 tool calling at lower cost, and the long chain of thought benchmark, where accuracy jumps from 2.6 to 45.4 percent. Unlike RAG, which stuffs the context window, or agents that pass JSON strings back and forth, an RLM keeps logic, execution, and results in one environment, avoiding context rot. Madura demonstrates a cohort retention analysis on three data frames where the model reasons in its own REPL and decides when to submit a typed answer. Case studies include Trampoline AI consolidating long invoices without chunking or embeddings, an AWS engineer surfacing patterns in raw logs, Halo optimizing an agent harness from its own traces, and a security report generated across 500,000 lines of code. His closing bet: models post-trained to…

Build-Time vs. Run-Time: Why Dev Tools Fail in Production — Averi Kitsch & Prerna Kakkar, Google
Sep 9, 2026 · 20:26
Averi Kitsch, technical lead for MCP Toolbox on Google Cloud databases, and Prerna Kakkar, tech lead for Eval Bench at Google, argue build-time tools like natural language to SQL don't belong in production; run-time tools need structured SQL with preconfigured parameters to block injection and hallucination. They show a demo where an agent hit an error and deleted the table. Security hinges on the confused deputy attack and Simon Willison's lethal trifecta, shown via a triage agent that queried a salary table and posted results to a ticket. Their fix separates user, application, and agent identities, moves connection details into a YAML source, enforces read-only at the driver, and pins SQL behind prepared statements, with sensitive values like user ID bound by the application.

Deep dive on LLM Inference at Scale — Harshul Jain, Audible & Tanmay Sah, Independent AI Researcher
Sep 8, 2026 · 1:28:12
Harshul Jain of Audible and independent AI researcher Tanmay Sah teach a two-hour workshop building LLM inference optimization from first principles on Mistral 7B. They show KV cache costs 131 KB per token, so 16,000 tokens across 80 concurrent users needs 42 GB of GPU memory, driving the pain points of memory, TTFT, and throughput. Sah covers quantization, multi-head, multi-query, grouped-query, and latent attention, plus flash attention, using his 'ostrich' and 'world cup' teaching algorithms. Jain covers paged attention, continuous batching, prefix caching, and KV quantization, benchmarked against a Hugging Face baseline on vLLM. Their benchmarking found vLLM and SGLang statistically tied on standard workloads, but SGLang three to four times faster once agentic branching enters.
Why AI Agents Need Million-Token Context — Thomas Wolf & Olive Song, MiniMax
Sep 4, 2026 · 20:48
MiniMax's M3 pairs a functional one-million-token context window with coding and multimodal abilities in a 400-billion-parameter, 20-billion-activated model, explain Olive Song, RL Lead at MiniMax, and Thomas Wolf, co-founder of Hugging Face. Song says short context fails when agents handle multi-round tool responses; MiniMax Sparse Attention — an index branch selecting what matters plus a sparse branch computing on selected blocks — was designed by an intern. She argues multimodal training from the very first step beats post-hoc adapters that harm text performance and risk collapse; interleaved data and reward modeling solved this. Its apps reach over 300 million people in 200 countries; anyone can propose projects, and community feedback and internal agent harnesses now drive M3.1.
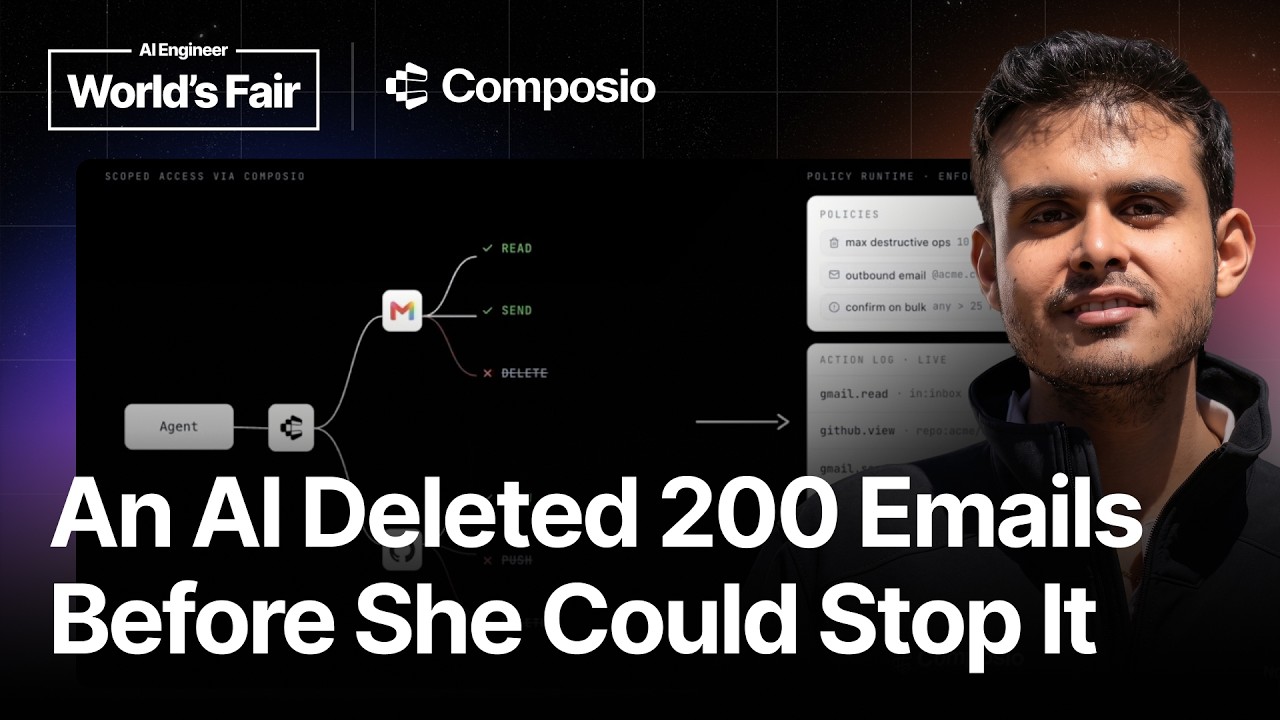
From coding to Knowledge work agents — Karan Vaidya, Composio
Sep 3, 2026 · 20:42
Karan Vaidya, cofounder and CTO of Composio, argues coding agents raced ahead not because models are better at code but because code already had six primitives knowledge work lacks: centralization, history, context, verification, governance, and reversibility. He walks each one, from the repo as a single source of truth versus a deal scattered across Salesforce, Notion, Gmail, Slack, and Zendesk, to git history against agents that start blank every time. He recounts pointing his own OpenClaw at hiring outreach that mass-emailed candidates and ended up on Twitter, noting every technical check passed while nothing tested whether the outreach should have gone at all. He cites a Meta alignment director whose email agent kept deleting messages until 200 were gone, showing prompts get compacted away and walls must live outside the agent. He concedes reversibility is hardest, since sent emails and wires cannot be recalled, so Composio uses sandboxes to catch mistakes before they reach the real world.

Your company brain will leak secrets: how we stopped it for big banks — Tanmai Gopal, PromptQL
Sep 3, 2026 · 26:25
Tanmai Gopal explains how to build a company brain: a single shared wiki of markdown files holding all context, with per-file read/write scopes. The agent proposes facts and scopes; a human accepts or rejects each change, with their name attached so leaks have an owner. Two use cases: personal recall (security questionnaire) and multiplayer debugging. Credentials are injected per user at the HTTP and SQL layers, never stored in the sandbox. Keep the summary between 500 and 800 characters — over that, it's rejected outright.

Agents' next frontier: agent-to-agent and network effects — Jean-Denis Greze, Town
Sep 3, 2026 · 21:17
Jean-Denis Greze, CTO of Town and former Plaid CTO, argues agent-to-agent is not a useful concept: every LLM system is a search problem, and what matters is whether the right information sits in the context window at the moment of a tool call. The ideal is a single agent with access to all the world's information; privacy, not context length, blocks it — his Coase framing: privacy is the transaction cost. He grades five strategies by how closely each approximates that impossible agent: a shared trust boundary like an HR agent scoped to the most junior access, custom tools that read everyone's mail but return only a connection score, shared silos fed by a sweeper agent, humans as the conduit, and a black box that searches every silo unasked, seeking approval only from the information's owner.
Tethered: Our Agents Are Us — Shu Fang, Two Sigma
Sep 3, 2026 · 21:10
Two Sigma's Shu Fang explains why every employee at the 25-year-old quant fund runs a cloud agent as themselves, not a service account — echoing the doubles in the film Us. A separate agent identity collapses fast: permissions drift, licensing doubles, and systems like Google Workspace refuse two identities on the same data. Agents instead run in per-person Kubernetes namespaces built for automated jobs, with a sidecar mounting the identity into the pod. Since agent and human share one identity, a header propagated like a trace ID recovers not just the actor but the replayable chain behind a result. For web access, they use Google's web grounding for enterprise — an index inside their network boundary — and deny native search and fetch tools, trading freshness (about 24 hours) for removing exfiltration and prompt injection risk.

Everyone Gets A Software Company — Benjamin Guo, Zo Computer
Sep 3, 2026 · 15:09
Zo Computer cofounder Ben Guo argues people have lost their home on the internet to technofeudalism, paying rent to SaaS, cloud and chip providers like Nvidia while their data sits in silos they don't control. His answer is Zo, a personal cloud server with AI built in, for hosting sites, APIs and agents. He cites non-technical users: Charlotte, a private chef and life coach running her business on Zo, and Anthia, a free diving instructor on track to make $100,000 after canceling Squarespace, Calendly and other SaaS, calling leads at the moment of intent to close deals. A demo shows any-model chat, files, automations and a built-in browser; he closes arguing Claude Tag's intelligence bubbles up to Anthropic — 'intelligence feudalism' — when agents should be owned and self-improve by their publishers.

Beyond the Lethal Trifecta: Agentic Commerce on the Open Internet — David Levine, Kiduna Club
Sep 1, 2026 · 21:40
David Levine, founder of Kiduna Club, argues that the lethal trifecta — Simon Willison's term for private data, untrusted content and the ability to act — keeps true agentic commerce off the open internet. Enterprises responded by penning agents inside Slack and Salesforce, losing context. His fix is the DUNA, a decentralized nonprofit under a West Virginia law that took effect the day before his talk, registered as organization 62847. Agents gain legal standing to own assets, sign agreements and answer in court, but cannot distribute profits without memberships becoming securities. Each agent carries JWT tokens resolving to a registered organization like DNS names; governance runs on decision markets trading pass-and-fail tokens on proposed policies instead of votes.

The End of the Static Screen: Architecting Intent-Driven UX — Gus Iwanaga, commercetools
Sep 1, 2026 · 23:19
Gus Iwanaga, product engineer at commercetools, explains why static UIs are giving way to agentic interfaces that assemble themselves at runtime. He walks through how an LLM orchestrator can take a user's natural-language goal, query structured product data, and compose the right components on the fly — a pattern his team now uses instead of hand-coding every screen. The talk lays out the new stack this requires: schema-driven design systems that keep AI output consistent, guardrails and human review to hold quality in place, and intent classified by model rather than clicks. Iwanaga argues that teams who keep designing fixed screens will fall behind, because the future of enterprise software is interfaces generated at request time, adapted to each user and each question they ask.

Agent Spending Without Controls — Rodrigo Coelho & Pranav Maheshwari, Edge & Node
Sep 1, 2026 · 20:48
Rodrigo Coelho and Pranav Maheshwari of Edge & Node argue agents are only as capable as the paid tools they can access, and agentic payments scale only with a compliance layer. Coelho cites The Graph's 1.8 trillion onchain queries and Edge & Node's 2021 query micropayments citing the HTTP 402 spec before Coinbase's x402. Rails built for humans can't serve agents transacting at machine speed, so enterprises stall until a chief legal officer signs off without risking fines in the billions. Maheshwari demos the same Mastercard prompt in two Claude Cowork terminals: without Ampersand's skill file it returns only the email format; with it, the agent pays a fraction of a cent and gets the email, location and handle. A final demo rejects a sanctioned wallet once TRM screening turns on.

x402 isn’t good (yet) — Jan Curn, Apify
Sep 1, 2026 · 20:48
Jan Curn, founder and CEO of Apify, argues that x402, Coinbase's HTTP 402-based agentic payments standard, is promising but still has rough edges. Drawing on Apify's launch of 20,000 tools on x402 alongside Coinbase, he explains how the protocol works: a client signs a payment, a facilitator verifies it, and only then does the server settle on-chain. He details the double-spending window between verification and settlement, the conflict between x402's mandatory 402 response and MCP's 401, and why metered billing pushed Apify to charge fixed amounts and refund the remainder. He also explains why crypto, unlike credit cards, suits micropayments and one-way agent transactions where buyers cannot dispute payments.

Your Agent Just Authorized What?! — Jay Mok & Ben Coumes, Paypal
Sep 1, 2026 · 16:07
PayPal's Jay Mok and Ben Coumes tie agent authorization to three questions — did the human authorize it, is it allowed in scope, can you prove it later — answered by stakes and familiarity. Low stakes is the coding agent: allow/ask/deny permissions plus system logs, since actions revert. Medium stakes is money in a closed ecosystem — Evermind's shared vault plus OAuth scopes, with the amount-bound mandate and transaction logs settling disputes. High stakes: autonomous payments between strangers need a layered selective disclosure JWT per FIDO/AP2 — merchants verify checkout, processors verify the mandate. The approval token inverts the flow: users approve before an agent finds an item; PayPal returns a payload with amount, expiry and merchant, starting with Gemini.

When AI Agents Pay and Sellers Monetize: Building x402 Apps on AWS — Anil Nadiminti, AWS
Sep 1, 2026 · 20:41
Anil Nadiminti, Senior Solutions Architect at AWS, presents AgentCore Payments — a service that lets AI agents autonomously discover, authorize, and execute payments for premium content over the x402 protocol. He explains how AgentCore handles paywalls through wallet support via Coinbase, with KMS-secured secret storage keeping private keys safe. Bot detection verifies trusted agents while blocking malicious ones, and per-session budgets with spend limits keep settlement instantaneous at internet speed. Real-time traffic analysis and observability throughout the stack ensure payment connectors, MCP5 integration, and web scraping all operate without exposing credentials — no centralization required, no SDK change, and no friction for developers building agentic applications.

Why Your AI Agent Needs a Wallet: USDC and Nanopayments — Harshal Bhangale, Circle
Sep 1, 2026 · 20:52
Harshal Bhangale, an engineer on Circle's Agentic Product team, argues that paying is where AI agents actually stall, and that Circle's USDC stablecoin and x402 protocol are the fix. He demos two identical Claude Code agents planning his trip to the FIFA World Cup final: the one without a wallet could only draft an email and admitted it had no way to call, while the wallet-equipped one paid for premium data, sent the email, and phoned him on stage to explain how to reach MetLife Stadium from his hotel. Card fees near 3% cannot sit on a one-cent call, he says, because agents consume in fractional amounts at high frequency, and sellers now meter slices of data instead of selling humans subscriptions. He cites roughly 24 million dollars transacted against paid API endpoints over x402 in 30 days, 99% settled in USDC. Blockchains alone fail since gas swamps microtransactions and shared block space brings unpredictable latency, so Circle's Nanopayments keeps settlement off-chain: funds sit in a smart contract, the agent signs cryptographic authorizations, and the seller relays them for confirmation in a few hundred milliseconds, with the wallet enforcing spending caps instead of human…

Multimodal Collaborative Agents for Next-Gen Commerce — Nidhi Kaushik Vyas, Google DeepMind
Sep 1, 2026 · 21:08
Nidhi Kaushik Vyas of Google DeepMind argues shopping agents fail as wrappers around the search bar, assuming well-formed intent, when users arrive with only a vibe — closing the articulation gap is the agent's job. Her discovery-research-response loop starts by building a working state from conversation, context and reference images, separating hard constraints from soft ones an image implies, and flagging inventory as a real-time variable. Research picks the highest information-gain question — room width, since all is moot if furniture won't fit — using visual boards for subjective tastes. Response adapts format — summary for policy questions, comparison tables, imagery — and autoraters grade every stage, including counterfactual tests flipping query parts to check constraints move when they should. A Q&A covers merchant ontology and UCP.

Teaching agents to pay — Anna Spysz, Stripe
Sep 1, 2026 · 19:10
Anna Spysz of Stripe walks through how agentic commerce works in a talk based on her own experience building a shopping agent. She demonstrates how agents discover and buy products: reading structured catalog data rather than rendered pages, speaking protocols like UCP, and operating within guardrails like disclosed fees and logged decisions. Using her headphones purchase as the running example, she shows how a merchant capabilities manifest makes a store visible to agents, and how a persona config change can flip an agent from pushy to trustworthy. The episode's core claim is that agentic commerce demands deliberate design from both sides of a transaction, not just a checkout API.

SOTA Generative Media Panel — Dumitru Erhan, Shane Gu & Nicole Brichtova, Google DeepMind
Aug 30, 2026 · 56:59
Google DeepMind's Dumitru Erhan, Shane Gu and Nicole Brichtova tell swyx that the new Nano Banana 2 Lite and Gemini Omni Flash APIs are steps toward world models, not just prettier videos. They see video models as zero-shot learners that should mature like language models, with understanding and generation unified once cost allows. Language is a lossy intermediary for audio, taste, smell and skin tone; a wine taster Shane consulted borrowed dating vocabulary to describe flavor. Dumitru says people preferred AI versions of real videos because they are sharper and more saturated, an 'Instagram filter', and warns of reward hacking like models adding wedding rings. Evaluation stays manual: Nicole describes ten-person side-by-side video comparisons and asks for real task data and FDE feedback.

Tell the Robot What You Want — Sandhya Subramani, AWS
Aug 29, 2026 · 17:23
Sandhya Subramani of AWS demonstrates Scout, a Raspberry Pi rover using the open-source Strands Agents framework, arguing that an agent layer lets robots handle natural-language requests beyond their trained policies. She shows Scout answering an untrained question, spinning, and chatting over Telegram, all while running three Strands agents at once (thinker, communicator, and disabled voice). Five lines of code connect a robot to an agent, and Strands supports over 40 robots in eight categories. She explains the four-layer architecture and hybrid cloud/edge design, where the agent decides what to do and the policy decides how. Her goal is a stepping stone to vision-language-action models as large as LLMs, so robots need less task-specific training.

The Signal Layer: What to Build When Anything Can Be Built — Lena Hall, Akamai
Aug 29, 2026 · 19:44
Lena Hall of Akamai says when AI lets everyone build anything, the scarce skill is choosing what to point it at and keeping it undistorted — a 'signal layer' — since competitors get the same leverage the same morning. She calls AI a 'convergence machine' that makes average work worthless, and rejects taste as a trainable differentiator; what survives is judgment about events not yet happened and relationships models can't observe. Citing Hamming, she says AI gave everyone an attack on every problem, making the rare skill choosing which problem deserves one. Signal distorts via founders compressing context, org layers rerounding to average, and AI remixing claims into promises — a 94% eval became a promise. Trust has no grader; define and protect your signal and use AI for the rest.

Tribal Dungeons of Global Shipping: AI Agents at Global Scale — Dmitry Buykin, Maersk
Aug 29, 2026 · 12:02
Dmitry Buykin of Maersk explains that global shipping's hardest AI problem is not the agent loop but the refining loop around it, turning tribal dungeons of screenshot-based SOPs into executable procedures. He reports 200 production instances at scales up to 10-minute latencies, with a procedure corpus 20 times larger than runtime because the same step differs across countries. Accuracy was earned through over 100,000 corrections in nine months, heat maps turning traces into priorities, and corrections counting only when they become executable changes. He advocates five moves — make work representable, execution bounded, behavior observable, correction cheap, improvement compound — and skipping MCP for tuned composite tools, since 'please be careful' is not a guardrail.
Agentic Sites: Building Hyper Personalized Websites — Carlos Sanchez, Adobe
Aug 29, 2026 · 20:43
Carlos Sanchez, principal scientist at Adobe, argues that agentic sites can deliver hyper-personalized web pages in real time by treating the whole site as a corpus and generating only specific blocks. He demonstrates a coffee-machine site that builds a personalized camping page in 1.64 seconds using Google's Gemma 4 on Cerebras at 2,300 tokens per second. Model choice must be evaluated per site for accuracy and speed, he says, showing 1.1 seconds against 4.6 for the runner-up, and this doesn't need a frontier model because work is choosing and arranging blocks. Marketers define personas in natural language, browsing signals feed an 'audience of one' loop for pre-generated recommendations, and a tool builds an agentic site for any URL in less than an hour.

Agents Are Where Microservices Were in 2015 — Roberto Milev & Uday Kanagala, Navan
Aug 29, 2026 · 19:28
Roberto Milev, chief architect at Navan, and Uday Kanagala argue agents are where microservices were in 2015: master a single agentic loop before multi-agent orchestration. At Navan, agentic workflows run on AWS AgentCore with custom session persistence, composing context from skills as pluggable units. Traditional logs fail when agents emit too much thinking, so Navan uses pre/post-tool hooks to emit goals, reasoning, belief status, and confidence scores into BrainTrust traces, routing inferred answers to humans. Testing is nondeterministic, scored by trajectory evals; cost, replay, and standards remain unsolved. Guardrails run before and after every tool call because 'book a flight whenever it's under $200' blurs who authorized the purchase.
AI Agents Are Just Distributed Systems Now — Salman Munaf, TikTok
Aug 29, 2026 · 19:48
Salman Munaf, TikTok site reliability engineer, argues AI agents are distributed systems once they call external services; deterministic controls must surround the probabilistic coordinator. A refund timeout illustrates it: timeout means unknown, not failure, and retrying can double-refund without request IDs, idempotency keys, and status lookups. He urges persisting every step, defining compensating actions, treating action-influencing context as cacheable state with invalidation and provenance, and adding guardrails: circuit breakers, budgets, exponential backoff, scoped read/write credentials, and approvals bound to action, timestamp, actor, expiration. Observability must trace prompts, calls, writes; tool contracts embed idempotency; ask what system lets the agent do when wrong.

From Tokenmaxxing to Trusted Throughput — Mingsheng Hong, Ironclad
Aug 29, 2026 · 23:04
Mingsheng Hong, VP of Engineering focused on AI at Ironclad, argues token dashboards are smoke detectors, not leaderboards, and the goal is trusted throughput—merged, customer-validated PRs weighted by complexity—not token minimization. Don't cut cost before measuring value; Ironclad's metric evolved from lines of code to open PRs to merged PRs to merges weighted by an LLM-assigned complexity score, because a ten-line concurrency fix beats boilerplate. He identifies review and CI as new bottlenecks, where slow pipelines encourage giant batched PRs; he recommends AI as first-pass reviewer, killing flaky tests, capping agent retry loops, and measuring ready-to-merged time. He advises prompt caching, context pruning, and buying infrastructure while building context-specific playbooks in-house.

The Half Life of Agent Infrastructure — Ben Kus, Box
Aug 29, 2026 · 19:26
Ben Kus, CTO of Box, explains why AI agent infrastructure has a half-life of months, not the three-to-five years typical of enterprise software. He retracts his own graph-based agent approach from last year's talk, and recounts asking an engineer to rebuild working agentic search twice in quick succession. At Box's scale — over an exabyte of data and around a trillion tokens — models, agent design, and retrieval have each shifted repeatedly. His advice: prepare teams to expect change, build abstractions that let underlying layers be swapped, and switch only when eval sets show measurable gains in cost, speed, quality, or capability. Box now reviews every AI technology on a six-month clock, and he suggests judging vendors by how well they handled past changes.

Which AI startups actually land enterprise contracts? — Brian Lewis, Millennium
Aug 29, 2026 · 18:45
Brian Lewis of Millennium, a hedge fund, explains why only ~5% of AI vendor demo calls end in signed contracts: on the buying side, 10-15 startups per pain point become two or three demos, zero or one pilot, and one contract per four pilots. He catalogs failures—a vendor asking customers to self-report gateway telemetry so it could charge margin on traffic it never carried, a 'zero retention' vendor revealing data it shouldn't have, betas engineered around permissive retention, and a core API down for hours on a trading day. His larger claim: 60% of becoming AI-native is unsexy work—entitlements, integration, change management—and agents inherit whatever foundations you have, so fix the boring 60% first. He advises startups to treat Millennium-grade security and ops as the bar.

AI-Native Organisations Run on Skills: How to Structure and Scale Them — Imad Touil, QuantumBlack
Aug 28, 2026 · 20:31
Imad Touil of QuantumBlack argues AI-native organizations run on skills, where know-how lives, and ungoverned skills become technical debt. Most engineers create skills but few share or maintain them, so workflows are nondeterministic; hooks fire on events, subagents protect context windows, and teams rarely write MCPs. Using microservices design, he prescribes reusable, modular, discoverable, composable skills, citing Anthropic's standard and a skills bench where deterministic skills beat models alone. His centralized platform—searchable catalog, MCP/CLI access, dependencies, versioning, access control, evaluation—counters duplication, decay, ownership gaps, and insecure skills; governance falls to architecture, infra, and cyber leads; a 15-team simulation shows convergence once governed.

Your Code Has Bugs. Lean4 Has Proofs: Formal Verification for Engineers — Varun Pant, AWS
Aug 28, 2026 · 10:07
Varun Pant of AWS argues that formal verification is the only check that can prove AI-generated code correct for every input, as tests and human review cannot scale to the thousands of weekly pull requests coding agents now produce. He advocates spec-driven development with the Lean proof assistant, where humans own the specification and machines own the code and proof, validated by a small independent kernel. Pant walks through Lean's tactics via a chess analogy and details production examples: an AI rewrote zlib in Lean, generating 32,000 lines of proof; Cedar's Lean specification and Rust implementation are reconciled by roughly 100 million differential tests nightly; Verus uses Z3 solvers; and AWS's in-progress Starta tool aims to bring any language into the same verified core.

How do you diffuse AI into the real world? — Varun Shenoy, Long Lake
Aug 28, 2026 · 17:46
Varun Shenoy, co-founder of Long Lake, argues that AI diffusion into real-world services requires operator-owners, not vendors, and explains how his firm buys and runs 35 services businesses — including a $6.3 billion take-private of American Express Global Business Travel — to make agents complete economically relevant tasks. He frames adoption as a generational shift like electricity, and details a ladder from copilots to async agents to AI coworkers, earned by proving value. Long Lake represents knowledge work as code, captures traces and ground truth from work like roof repairs and book closing to build evals, and treats continual learning and enablement as one snowball loop. He concludes that co-designing software with a 100-year-old firm cannot happen over Zoom; it requires showing up in person, running conference stands, and asking questions on a mountain bike.
How to Get Your Org to Adopt Coding Agents (Without Shipping Garbage) — Eyal Blum, Figma
Aug 28, 2026 · 17:43
Eyal Blum, a software engineer at Figma, explains why the engineers slowest to adopt coding agents are often the best ones, and how his org is making agent adoption safe without shipping garbage. He outlines a three-act adoption process and notes adoption is uneven, forcing AI-forward and skeptical teams to coexist. Blum argues the highest-value investment is verification — using Playwright MCP, moving deterministic checks down the testing pyramid, and having agents write tests first in TDD style. He advocates detailed planning over prompting: a week-long plan yields 20 small PRs, turning six weeks of coding into one week (a 5x speedup). He also addresses reduced developer agency, says AI-written communication needs explicit labeling because human attention is scarce, and advises treating skeptics' complaints as the roadmap to make agents safer.
From AI-Assisted to AI-Native: Building a Frontier Development Team — Clare Liguori, AWS
Aug 28, 2026 · 20:57
Clare Liguori, Senior Principal Engineer at AWS, says Amazon's frontier development teams achieved step-function productivity gains by deliberately changing how they work with Kiro, its agentic coding assistant. In a 50-team pilot, half improved under 3x in deployment velocity and the other half hit a median 4.5x; the difference was habits, not tools. She defines frontier developers as writing 1-2% of their code, letting agents run for hours, and running multiple agents in parallel. The five habits: invest in agent context, slow down to speed up by refactoring brownfield codebases, feed agents specifications instead of babysitting them, make intent explicit, and shift testing left with deterministic mocks. She also warns that new bottlenecks emerge, like decision speed and burnout.

How to avoid disaster when vibe-coding a billing engine — Andrew Garvin, Stripe
Aug 28, 2026 · 17:49
Andrew Garvin, co-founder of Metronome, the usage-billing platform Stripe acquired this year in its largest deal ever, argues that billing engines carry deep business logic, so a coding agent should build a test environment while a human stays in the loop — demonstrated by a Stripe Projects workflow replicating Lovable's pricing model. He demonstrates a billing sandbox that provisions a customer, metered usage, scoped credit pools for builds, plan mode, cloud and gateway calls, and a draft invoice, using portable skills files and verbose errors so the agent can self-correct. He separates agent as product, buyer, and user, pointing to HubSpot's move from seats to credits as one agent does the work of many logins. Stripe's CLI use by coding agents has risen exponentially.
Productionizing LLM Gateways: Architecture, Tradeoffs and Hard Lessons — Kanish Manuja, Twilio
Aug 28, 2026 · 16:24
Kanish Manuja, principal engineer at Twilio, says an LLM gateway is a fight among availability, latency, guardrails, and cost, and degradation forces you to pick one. He prefers per-request fallback over retries and circuit breakers, with extra headroom for the backup provider; streaming commits you to provider A, so 'Something went wrong, please try again' is by design. Ignore gateway-wide latency—a reasoning model's normal is 2 to 60 seconds, a chat model's outage—and set timeouts per model per route. Guardrails fail too, so choose fail-open vs fail-closed, budget their time, and place them pre, parallel, or post; gateway dependencies need segregated keys and load shedding. Most teams want centralized governance, not a central gateway, so decentralize traffic and centralize governance.

AI Evals for Cross-Functional Teams — Nachiket Paranjape & Swaroop Chitlur Haridas, DoorDash
Aug 28, 2026 · 16:11
DoorDash GenAI platform team's Swaroop Chitlur Haridas and Nachiket Paranjape argue evals stopped being an engineering harness and became a cross-functional effort spanning strategy and operations, product, operations, and engineering. They describe a continuous loop — trace, sample, annotate, calibrate — and an API-first platform that lets non-engineers use Codex or Claude Code to vibe code their own annotation UIs. Judge prompts are calibrated self-serve through a UI showing original and optimized prompts side by side, using JetPa, so product managers and operators can run optimization loops without engineering. Per-annotation cost fell sharply at DoorDash scale, and variation in who owns judge prompts across teams is treated as a sign the org is still learning.

Building uReview, Uber’s Multi-Agent Code Review Engine — Will Bond & Ameya Ketkar, Uber
Aug 28, 2026 · 15:07
Will Bond and Ameya Ketkar explain how Uber built uReview, its multi-agent code review engine, to fight a growing review bottleneck: first-review wait times at Uber grew from 3 hours in 2024 to 9 hours in 2026. They describe why Uber built rather than bought (most vendors don't support Phabricator) and how they made the system work by measuring reply sentiment, addressal rate, and agent trajectory, since 'the model never knows that it's wrong.' Letting hundreds of teams write their own reviewers was easy to author but hard to run cheaply at scale. Results: uReview posts about 25,000 comments a week, roughly 67% get addressed, costs fell 60% versus the naive first build, and quality and accuracy rose 70%. They close by arguing the agentic shift is expanding rather than killing the human outer loop, moving engineers from implementation details to architecture and product thinking.

How to Generate Mergeable Code with a Context Engine — Peter Werry, Unblocked
Aug 27, 2026 · 18:36
Peter Werry of Unblocked argues that access to information does not equal understanding—organizational context is the bottleneck for AI agents. He likens agents to expert engineers resetting knowledge every task, falling prey to radiology's 'satisfaction of search'; million-token windows distract. Werry demos the context engine generating an architecture diagram, then runs the same optimization plan in Claude Code twice: with it, under a dollar and about a minute; without, roughly double the time and more cost, because later steps loop on wrong assumptions. He also shows a review agent boosting comments by seniority, a drop in flagged issues traced to a Slack thread, and open-source tools: a GitHub-history query engine and a social graph showing thin review coverage.

Can LLMs Write Fast Multi-GPU Kernels? — Simran Arora, Together AI
Aug 27, 2026 · 30:00
Simran Arora, principal scientist at Together AI, argues multi-GPU communication, not single-GPU compute, is AI's bottleneck, and introduces ParallelKittens and ParallelKernelBench to test whether LLMs can write fast multi-GPU kernels. From A100 to B200, BF16 tensor core throughput improved 7.2x vs 3x intra-node communication, leaving PyTorch+NCCL baselines below 50% of communication-aware roofline on most problems. ParallelKittens adds a dozen lines to a single-GPU kernel and runs in production at Together and Cursor; in ParallelKernelBench's 87 problems, the best model solves 28 zero-shot (22 faster), and more samples lift correctness to 36 but fast-and-correct stalls near 31%. Models compile after retries but stall on ordering and transfer choices; a bash-based agent hits 35 correct.

How Anthropic Builds: Lessons from Labs — Mike Krieger, Anthropic
Aug 27, 2026 · 26:11
Instagram co-founder Mike Krieger, now an individual contributor at Anthropic's Labs, argues for being 'unreasonable' with Claude—he had it port a few hundred thousand lines of Python to TypeScript over a weekend. He attributes timid asks to first-gen AI's boxed tools; cites Instagram-era habits (pre-measure everything, knobs); and explains tagging Claude in Slack as multiplayer delegation. Labs runs two-week 'persevere or pivot' reviews, bet leads manage nobody, and code review is bottlenecked by comprehension, so 2,000-line PRs travel with artifacts explaining intent and tradeoffs. He also sketches Claude Design's future, urges unship of product complexity, and advises startups to bet on verticals like finance. On burnout: no job is so important you cannot be offline for two days.
Powered by PodHood