Productionizing LLM Gateways: Architecture, Tradeoffs and Hard Lessons — Kanish Manuja, Twilio
Aug 28, 2026 · 16:24
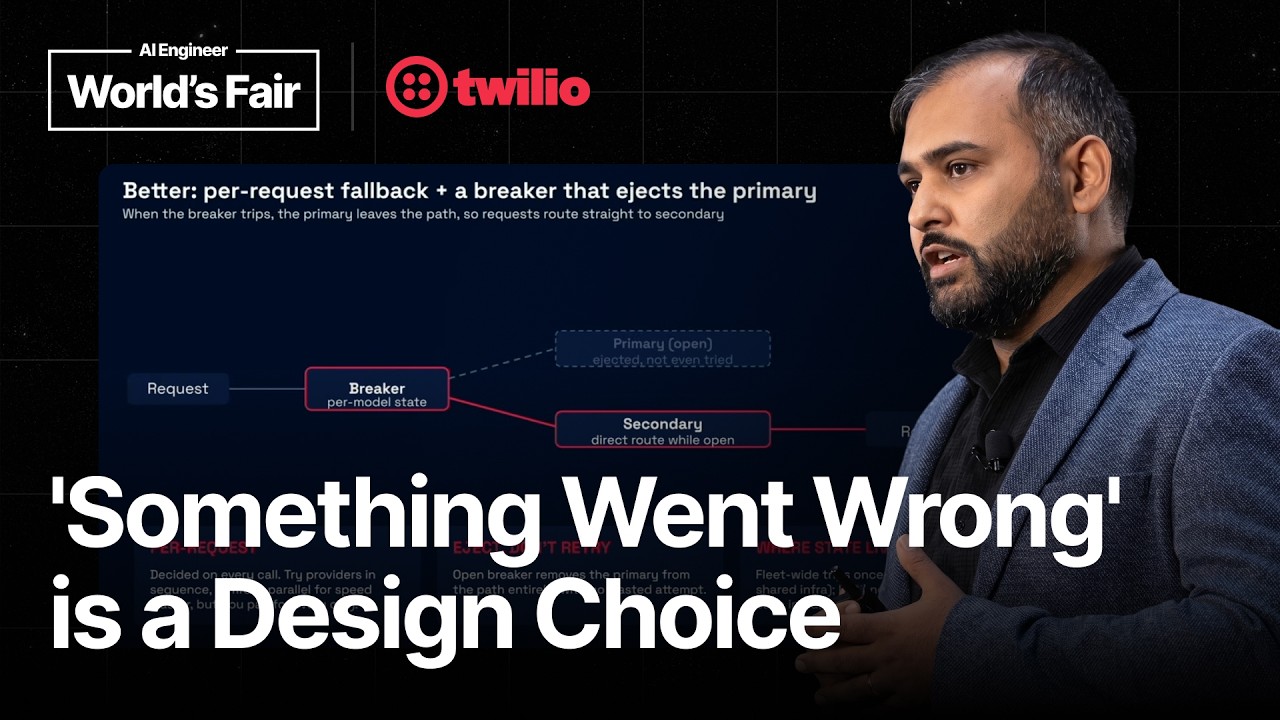
Kanish Manuja, principal engineer at Twilio, says an LLM gateway is a fight among availability, latency, guardrails, and cost, and degradation forces you to pick one. He prefers per-request fallback over retries and circuit breakers, with extra headroom for the backup provider; streaming commits you to provider A, so 'Something went wrong, please try again' is by design. Ignore gateway-wide latency—a reasoning model's normal is 2 to 60 seconds, a chat model's outage—and set timeouts per model per route. Guardrails fail too, so choose fail-open vs fail-closed, budget their time, and place them pre, parallel, or post; gateway dependencies need segregated keys and load shedding. Most teams want centralized governance, not a central gateway, so decentralize traffic and centralize governance.