
Anterior
CompanyA company discussed on AI Engineer.
3 episodes

Don’t be data poor — Anuj Iravane, Anterior
Aug 19, 2026 · 16:46
Anuj Iravane, who leads AI at Anterior, explains why the company builds synthetic medical data by reversing its inference workflow: the real faxed records it needs most are protected patient data its contracts forbid keeping. With about 70% of medical communication still moving by fax, Anterior starts from a label, samples a reasoning trace from policies modeled explicitly as decision trees, then builds a coarse-to-fine patient journey and documents, making labels correct by construction. Clinicians own the pipeline as interchangeable skills, and roughly 90% of datasets are now synthetic; in a blind review they separated synthetic from real only about 60% of the time. The payoff is creating edge cases on demand and testing workflows before deployment instead of waiting on customer data.

Make your LLM app a Domain Expert: How to Build an Expert System — Christopher Lovejoy, Anterior
Jul 28, 2025 · 19:18
Christopher Lovejoy, a medical doctor turned AI engineer at Anterior, argues that building a domain-native LLM application requires a system for incorporating domain insights rather than relying solely on model sophistication. Anterior's Adaptive Domain Intelligence Engine uses domain expert clinicians to review AI outputs, generate metrics, define failure modes, and suggest improvements. This process improved Anterior's clinical reasoning tool from 95% to 99% accuracy on medical necessity reviews for health insurance providers covering 50 million lives. By enabling same-day iteration—production cases reviewed, failures categorized, domain knowledge added—the system solves the 'last mile problem' of giving models nuanced understanding of customer workflows. Lovejoy emphasizes that the limitation is not model reasoning but encoding domain-specific context, and the winning vertical AI team will build the best system for this translation.
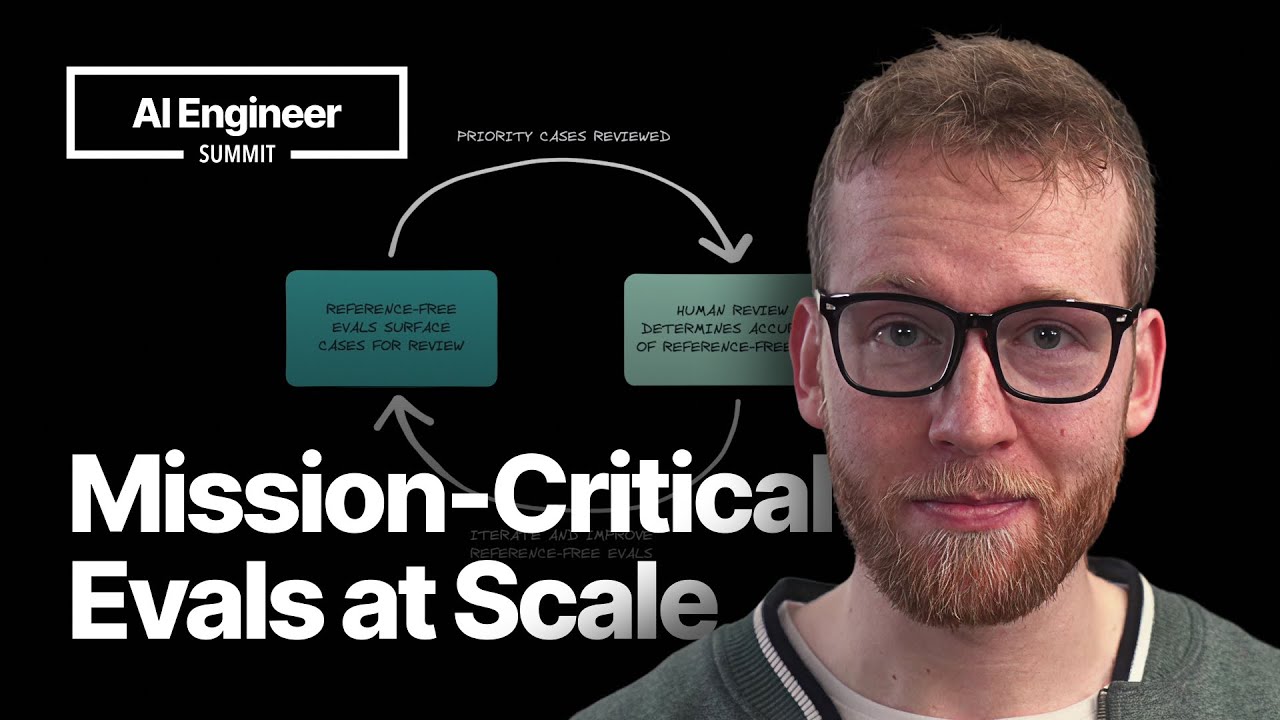
Mission-Critical Evals at Scale (Learnings from 100k medical decisions)
Feb 22, 2025 · 12:15
Christopher Lovejoy, a medical doctor turned AI engineer, explains how Anterior built a real-time reference-free evaluation system to scale mission-critical AI decisions in healthcare to 100,000 per day while maintaining trust. He shows that human reviews don't scale (50 clinicians needed for 5,000 daily reviews) and offline evals miss new edge cases. Instead, Anterior uses an LLM-as-judge to assign confidence scores, dynamically prioritizing high-risk cases for human review. This 'validating the validator' system achieved a 96% F1 score in prior authorization, letting a team of under 10 clinical experts handle tens of thousands of cases. It provides real-time performance estimates, enables rapid error correction, and builds defensibility through proprietary data and iterations only possible at scale.
Powered by PodHood